Context gives the model something to work with
AI & RAG
The interesting work begins where a model meets the data, the interface and the person using it.
AI as part of a product
My work spans LLM integration through APIs and retrieval-augmented generation: embedding models, vector databases and filtering to search by meaning. I build the application around the model — data pipelines, backend services and the interface people actually use.
Assistants over real data
In Urbano, a RAG assistant is grounded in 22,300 city documents. The assistant belongs to the same civic platform as the citizen app, administrative console, public API and government forms. Retrieval and the surrounding product give the conversation its context.
Retrieval can be visual
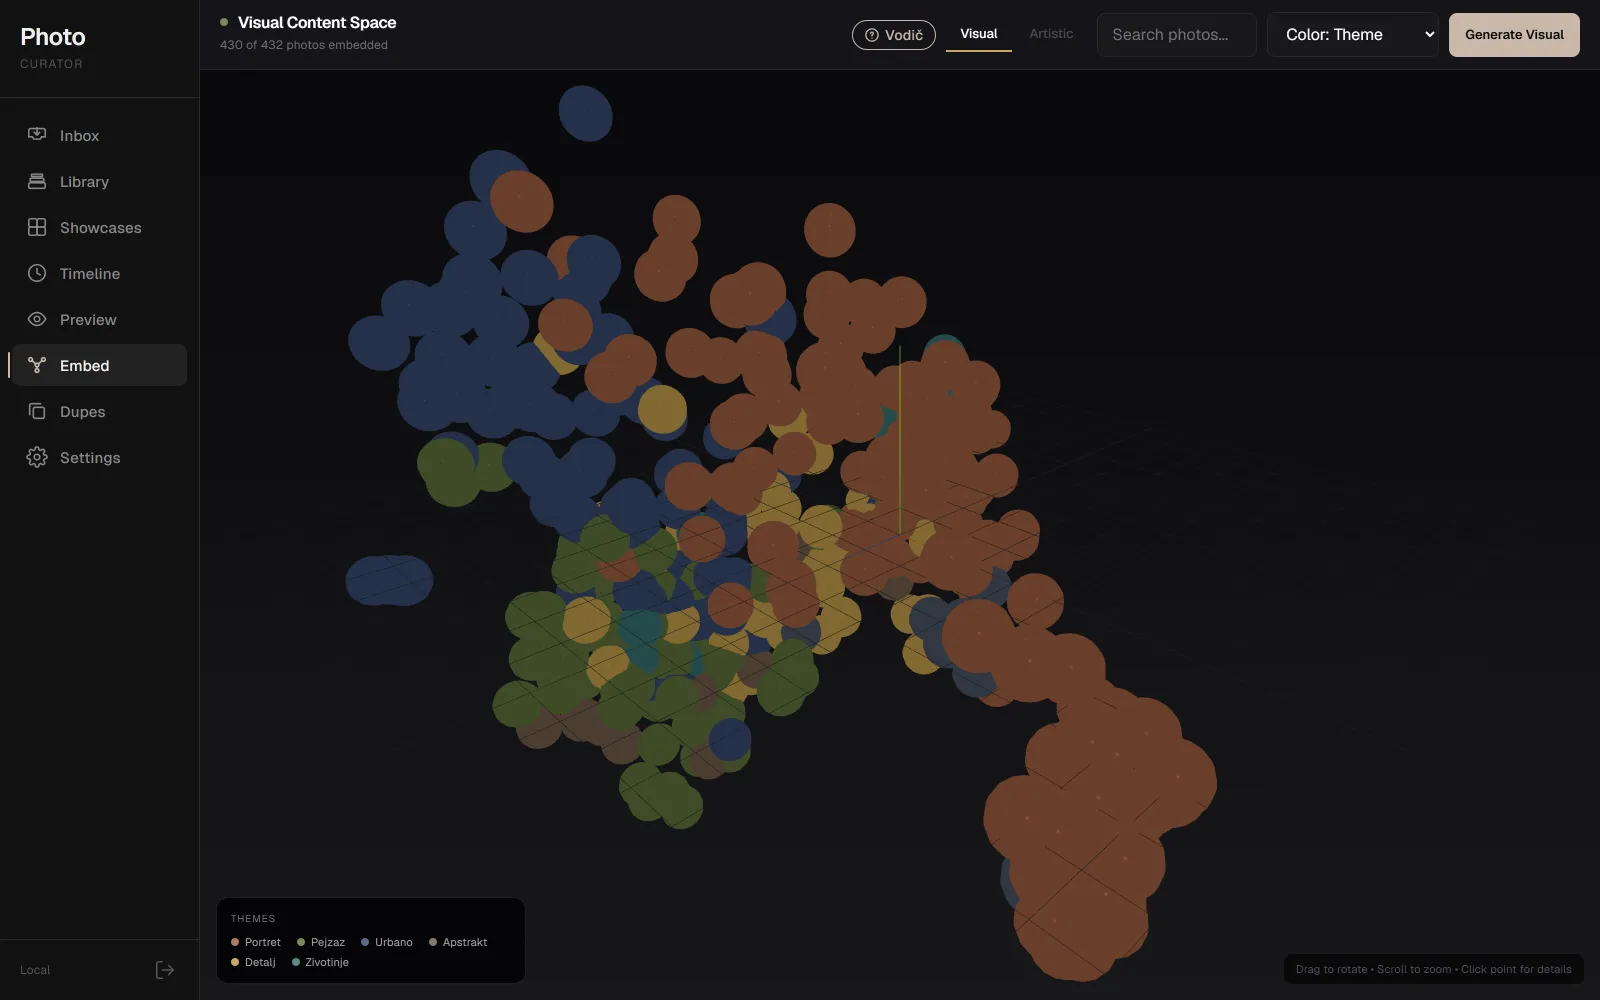
Curation Engine reads a photographic archive through multimodal and text embeddings. Cosine similarity powers visual and semantic search; clustering surfaces connections between frames, and the retrieved photographs become context for generation.
The human part of the interface
Conversational flows, fallback mechanisms and relevance evaluation give people a way to work with the output. In the curation system, a photographer can steer a description through conversation and make their own selections.
From architecture to production
The work includes the services around the model: React interfaces, Node.js APIs, data stores, object storage and deployment. In Curation Engine, the dashboard and public portfolio run on Vercel, the API on Railway, originals on Cloudflare R2 and the models on Vertex AI.
Working together
Send me the product context, the data you have and what the system should help someone do. We can discuss scope and approach by email or on a short call. I am open to project collaborations and full-time roles.